/ 01
Voice-Optimized GPU Clusters
High-performance GPU infrastructure purpose-built for real-time speech, ASR, TTS, and LLM inference.
© 2026 Machine Path Industries. All rights reserved.
Dedicated high-density GPU bare metal and low-latency orchestration tuned explicitly for real-time speech, LLM inference, and telecom-grade scaling.
Talk to SalesHigh-performance GPU infrastructure purpose-built for real-time speech, ASR, TTS, and LLM inference.
Ultra-low latency networking, carrier integrations, and production infrastructure designed for voice workloads.
Deploy, monitor, and scale production voice AI services from a unified management platform.
MPI runs single-tenant, liquid-cooled superclusters from institutional-grade facilities designed for high-density compute workloads. No virtualization penalty. No shared memory. Secure, isolated compute on demand.
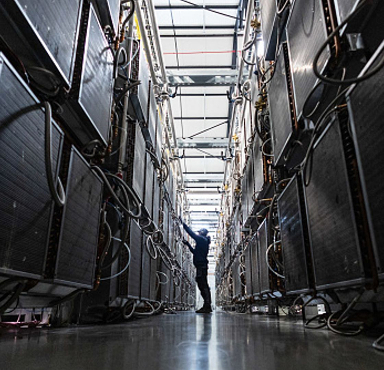
MPI designs its infrastructure around the latency needs of real-time voice workloads.
Single-tenant servers, dedicated private keys, and fully isolated network fabrics.
Our engineers deploy, fine-tune, and optimize custom speech models directly to your clusters.
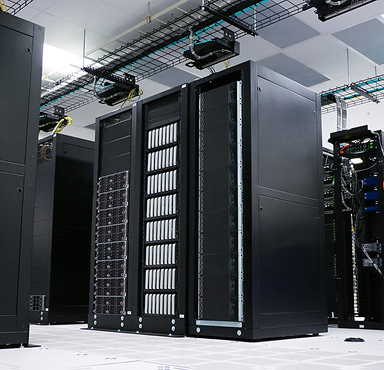
Hardware faults trigger live failover without interrupting customer conversations.
Most GPU providers ignore telecom interfaces. MPI operates where these systems collide, transforming traditional VoIP trunks into blazing-fast AI compute paths.
Partners & Ecosystem
Dedicated high-density GPU bare metal and low-latency orchestration tuned explicitly for real-time speech, LLM inference, and telecom-grade scaling.